AWS Details Centralized Observability Data Lake for Amazon Bedrock Invocation and Cost Tracking
Enterprise AI
AWS published an architectural guide and sample repository for building a centralized Amazon Bedrock observability data lake. The pattern aggregates cross-account model invocation logs using Amazon CloudWatch, Lambda, Amazon Data Firehose, and Amazon Athena. By joining invocation metrics with Cost and Usage Report (CUR) data, organizations can analyze token consumption, prompt efficiency, and per-call expenses across teams.
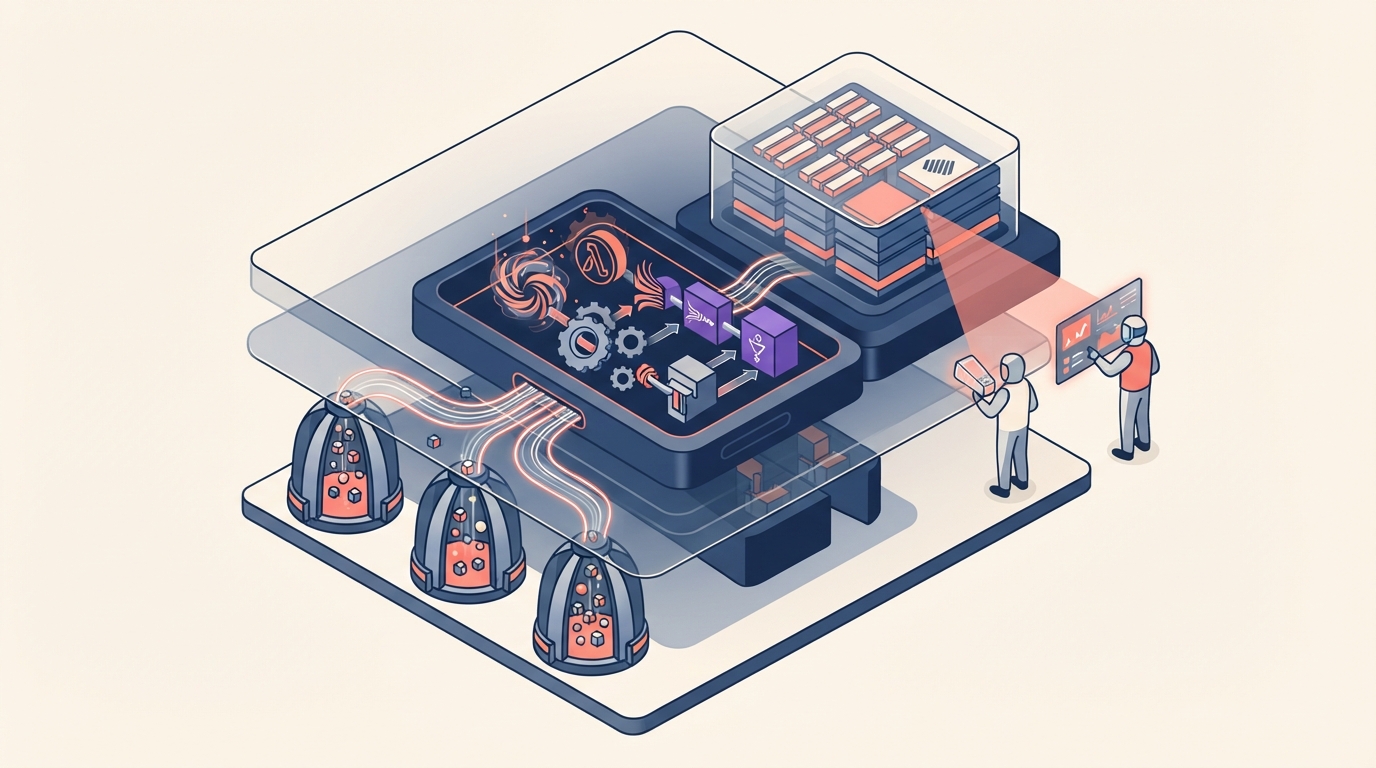
AWS shared an architecture pattern to help platform and machine learning engineers manage token economics across distributed Amazon Bedrock environments. While native Bedrock logging captures detailed request payloads and token counts, records typically remain siloed across individual AWS accounts. The solution establishes a cross-account ingestion pipeline deployed via AWS CloudFormation templates. Under this design, linked accounts enable Bedrock logging to Amazon CloudWatch log groups, which use subscription filters to push records to a centralized account. In the central pipeline, an AWS Lambda function strips service noise, unbundles event batches, and flattens caller identity fields. Amazon Data Firehose converts the JSON payloads into partitioned Parquet files stored in Amazon S3, allowing teams to query invocations via AWS Glue and Amazon Athena. The resulting dataset captures prompts, model outputs, token volumes, selected models, stop reasons, timestamps, and IAM roles. AWS noted that joining these records with AWS Cost and Usage Report (CUR 2.0) data via IAM ARN enables granular cost attribution, identifying expensive prompts and team usage trends. Visualization is supported through an AWS QuickSight dashboard deployed via the Cloud Intelligence Dashboards framework.
Key takeaways
- AWS released a sample repository and CloudFormation templates to aggregate Amazon Bedrock invocation logs across multiple accounts into a centralized data lake.
- The data flow routes logs through CloudWatch subscription filters, Lambda preprocessing, and Amazon Data Firehose into Parquet format on Amazon S3 for Athena SQL queries.
- Flattened logs capture prompts, responses, input and output tokens, models, timestamps, stop reasons, and caller IAM roles.
- Joining query results with Cost and Usage Report data allows engineering teams to map token usage to specific department spend and identify inefficient model prompts.
Source:AWS Machine Learning Read the original ↗
Prepared, checked and automatically published by AI; not individually reviewed by a human.